Someone clicks an advertisement and later buys. The campaign receives credit. The useful next question is whether that person would have bought anyway.
That question sits beside a more visible change in OpenAI’s October 5 announcement : a planned visual-ad test during ChatGPT image generation. The company scheduled an initial US advertiser group for later that October. It said ads would be labeled, separate from the requested image and independent of ChatGPT’s answers.
The screen and the sales report deserve different kinds of attention. On screen, can someone recognize the paid message? In the report, does a credited purchase establish additional business? Bringing those questions together makes the announcement easier to assess without treating them as the same problem.
A creative task needs a readable boundary
A person asking for an image already has something underway. It might be a room idea, a meal or an illustration. An advertisement appearing nearby introduces a second message into that activity.
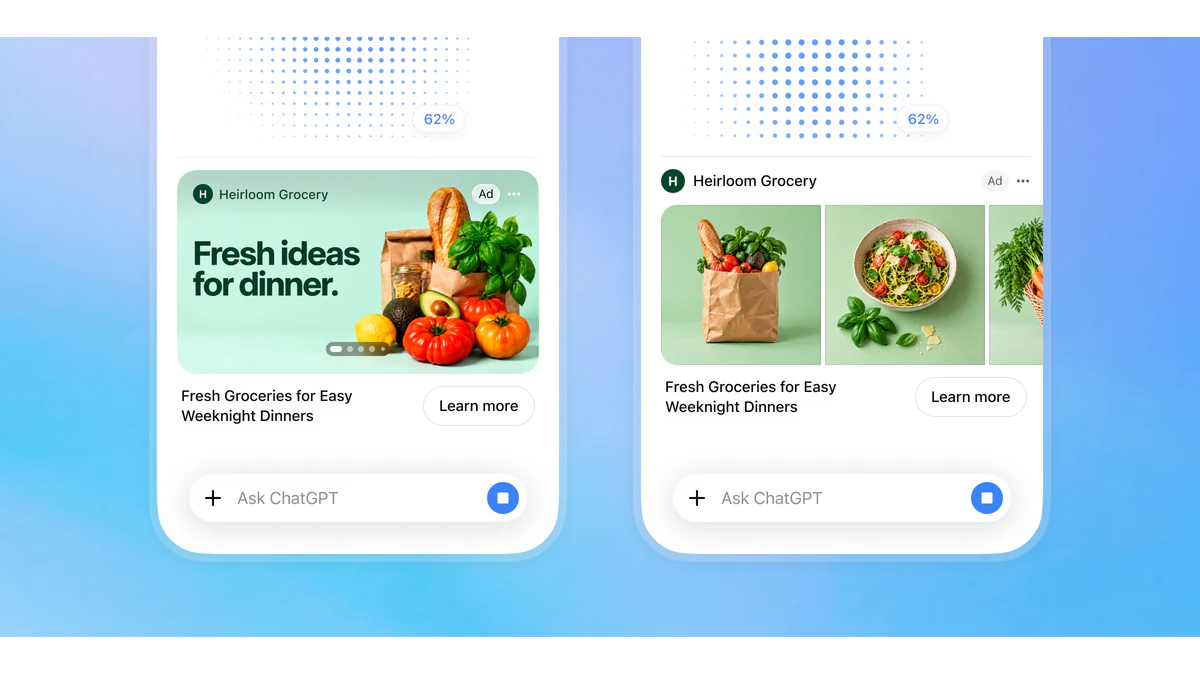
The sponsored unit, the model’s response and the image being created need to remain recognizable. A label identifies paid placement. The surrounding layout helps explain which part of the experience the label applies to.
OpenAI’s published illustration shows two proposed Heirloom Grocery layouts, each with an ad marker and a destination button. It is a product-interface example. It does not establish the grocery business’s qualities or a merchant relationship a reader should act on.
Look at the boundary before considering the advertised product. Would someone understand where the paid unit begins and ends? Could they continue their original task without mistaking it for part of the requested image? Those are useful evaluation questions, rather than findings from a user test presented here.
Proximity is a design choice with consequences for attention. A clear boundary gives the person a way to decide how to treat the second message while continuing with the first.
A credited sale answers a reporting question
The measurement announcement describes connecting campaign information with advertisers’ existing systems and conversion events. A purchase, lead or other defined action can become part of the reporting relationship.
Attribution assigns credit according to a rule or model. If someone clicks and buys within a defined window, the report may credit the campaign. That can help organize a customer journey and reconcile figures across services.
The definition needs to travel with the number. What counts as a purchase? How long after an interaction can it receive credit? Which earlier interactions are considered? Which costs belong in the comparison?
For an illustration, compare a one-day window with a seven-day window. A purchase on day three could qualify under one and fall outside the other. The observed purchase is unchanged, while the credited total can differ. These are example windows, not a claim about the platform’s available settings.
That makes attribution useful for its defined job. It does not recover the same customer’s alternative future without the advertisement.
Ask what changed because the ad ran
Incrementality concerns that alternative. How much additional business occurred because of the campaign? A purchase can satisfy an attribution rule while still being one the customer would have made anyway.
In the October announcement, OpenAI described its incrementality work as early and said partners were exploring geographic experiments. A comparison between exposed and comparison areas offers a route to estimation, with the design determining what the result can support.
A useful experiment needs a defensible comparison, a defined outcome and attention to other changes affecting it. An area receiving advertising may differ from another before a campaign begins. A seasonal shift or another promotion may also influence sales. The word “experiment” does not settle those questions by itself.
Attribution and incrementality can then be read together without being collapsed into one success measure. One organizes credit for observed journeys. The other investigates whether the total outcome changed because of the spending.
The AI feedback-loop analysis follows a related habit: trace where a benefit appears and what work or cost sits around it. A convenient interface and a convincing metric both become more useful when their boundaries are clear.
A policy and an evaluation supply different evidence
OpenAI also described controlled brand-suitability pilots with external partners, without access to private user conversations. That was the announced evaluation approach, rather than a completed independent finding for every placement.
The advertising policies supply the published rules. A rule defines an intended standard. An evaluation examines performance against a standard in a specified setting. Ongoing monitoring concerns what happens after operation begins.
For an evaluation report, look for the scenarios, criteria and results. A partner’s name tells you who is involved. The method and findings explain what the exercise establishes.
Conversation privacy belongs beside that assessment, with its own questions. An advertiser measuring conversions in its systems is not, by that fact alone, describing access to a user’s chat. A controlled test scenario is also different from a private real-world conversation. Keep the data involved in each activity explicit.
Carry two questions through the announcement
The October plan establishes the proposed test’s timing and scope. It does not establish availability in every account or a completed result. The published layouts give readers a place to begin examining the idea.
On screen, look for a paid message that can be recognized as such. In the report, look for a number whose definition is visible and whose causal meaning is supported.
Return to the person who clicked and bought. The report may correctly assign credit. Understanding what the campaign added takes another question, and another kind of evidence.
FAQ
What did OpenAI announce about ChatGPT visual ads on October 5, 2026?
It planned an initial US test later that October during image generation, with labeled ads separate from the image. The announcement alone does not establish universal account availability.
How can an advertisement get credit without creating an extra sale?
The purchase may qualify under an attribution rule even if the customer would have bought anyway. Incrementality asks what additional outcome the campaign caused.
Does an external suitability partner’s involvement prove every placement is safe?
No. Read the evaluation’s scope, method and findings. The announced controlled pilots are distinct from completed validation of every placement.