A book appears on a writer’s author page, and a buyer reasonably assumes it belongs to that writer. The text has borrowed credibility before anyone reads a line. September reporting on Amazon publishing, a military intelligence episode and FAA decision support shows how a surrounding system can give an output authority it has yet to earn.
The common problem is an authority gap: the distance between what an output establishes and what its screen, template or attached identity encourages someone to believe. Following that gap gives us a more precise question than whether AI sometimes makes mistakes. Where did the result become a record that another person was expected to trust?
Follow the handoff into a trusted record
Consider the handoff. A route suggestion enters an air-traffic workflow. A chatbot conclusion is placed in an intelligence-report template. A disputed book listing joins an established author’s profile. Each destination already has a purpose and a history of use. That familiar setting can make the new material look as though it has passed the same checks.
That dynamic overlaps with automation bias , the tendency to favor an automated suggestion even when other information points elsewhere. Yet the three stories show something broader than individual overtrust. Institutions decide which screens, templates, profiles, and queues an output can enter. Those design choices determine how much authority it receives before anyone checks its basis.
A human reviewer needs more than an approval button. They need the source, the uncertainty and enough time to inspect them, along with authority to send the result back. Otherwise, adding a person to the workflow can leave the original assumption untouched while giving it another apparent stamp of approval.
A route suggestion still needs an operating decision
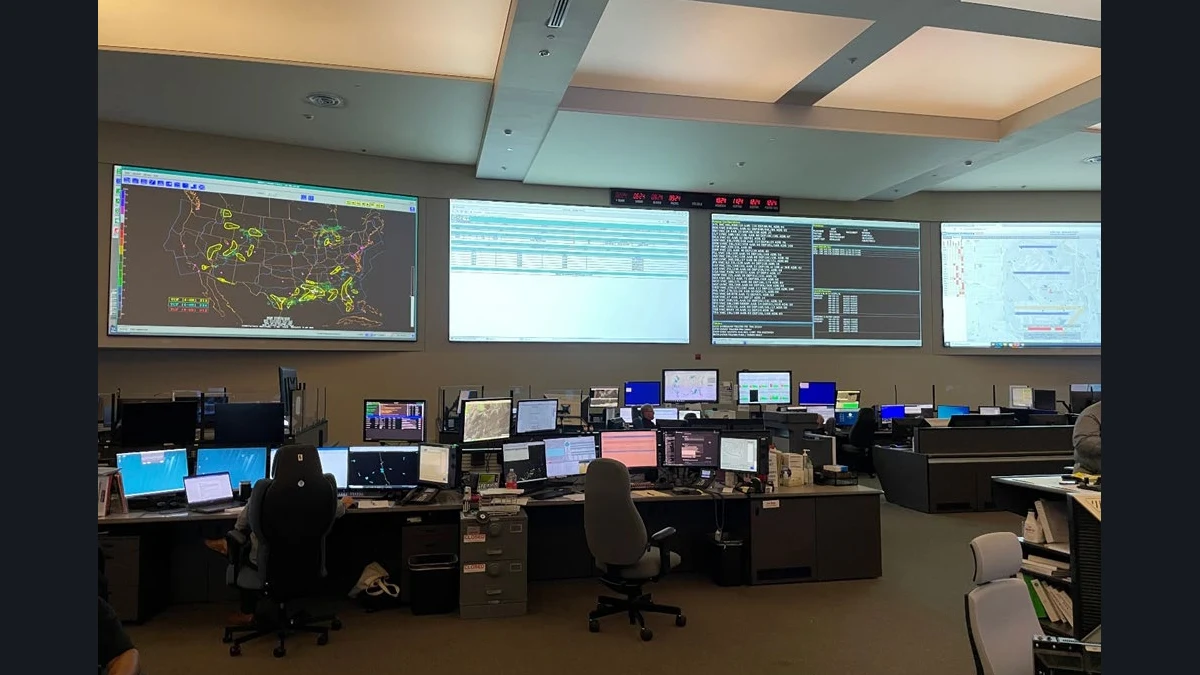
The FAA’s June announcement describes Flow Management Data and Services as the data backbone for traffic-flow management. Its SMART enhancement would combine schedules, weather, airport capacity and airspace conditions to anticipate congestion and conflicts. The proposed role is to bring information together early enough to improve the available options.
In the September account, Ars Technica reports a possible start at the three major Washington-area airports. The 12-year Air Space Intelligence contract covers SMART and the larger FMDS replacement. The specific model class behind SMART remains publicly unspecified in that reporting. Treating it as a chatbot would import an unestablished technical assumption into the comparison.
The operational boundary is more important than the label. Politico reports that airline concern eased after the FAA explained that the first phase would not create new procedures for controllers or carriers. SMART would generate alternative-route information, pass it through existing FAA systems, and undergo a roughly 90-day test focused on predictive performance and airline confidence.
That limited role makes the next evidence easier to define. Does the recommendation remain useful in unusual weather, with degraded data or when operators disagree? A staged test can examine those conditions while existing processes retain operating authority. The tool’s screen should make the recommendation available for judgment without making its polished presentation stand in for performance.
The surrounding programme still requires scrutiny. A September GAO review says the broader air-traffic modernization effort needs stronger cost and schedule planning. SMART may improve route options without solving staffing, ageing infrastructure, integration, or programme-management problems. Keeping those claims separate protects the system from inheriting authority for outcomes it does not control.
A familiar report can hide an uncertain inference
CNN reports that an analyst used a chatbot while examining intelligence about a Chinese ship during the war with Iran. Citing four people familiar with the matter, its September account says the tool misidentified cargo, the conclusion entered a standard intelligence report and a deeper review stopped a planned interception. CNN said the Pentagon and U.S. Special Operations Command Pacific did not respond. The episode remains attributed to that reporting, rather than an established official finding.
If the account is accurate, the critical handoff came when an uncertain chatbot conclusion became an intelligence product. A later reviewer needed to see what was collected, what was inferred and who checked the difference. That trace would make the central claim open to challenge before an operational decision.
A standard template can conceal that distance. The document may look familiar even if its central inference comes from a tool the reviewer cannot identify. Keeping source material, model inference and analyst judgment visible as separate steps gives the next person a way to examine how the conclusion was reached.
The department's official AI acceleration strategy calls for wider use across warfighting, intelligence, and enterprise operations. That policy does not confirm CNN's report. It does make provenance controls urgent. A consequential intelligence product should retain which data came from classified collection, which came from open sources, what the model inferred, what the analyst changed, and which uncertainty survived review.
An author page lends a book someone’s name
In publishing, the authority gap appears through identity rather than operational command. The Atlantic documents multiple writers who found suspected AI-generated titles associated with their Amazon author pages or names. In several cases, books were detached from a real author's profile after a complaint but remained available for sale under the disputed author name.
For a buyer, the author page is a shortcut through a crowded marketplace. A familiar name helps decide which book deserves attention. If a disputed listing is attached there, that shortcut can lend the title a connection it has not earned. Removing only the profile association may still leave the same disputed name on a book for sale.
Amazon’s KDP content guidelines require disclosure of AI-generated content to Amazon and place responsibility for rights on the publishing account. Knowing how text was generated is useful. Confirming whose name belongs on it is another check. A platform can receive the first disclosure while still attaching a title to the wrong person.
The Authors Guild's Human Authored programme illustrates a stronger provenance pattern. It combines a registered title, a searchable public record, and identity verification. Certification cannot police an entire marketplace, but it demonstrates that authorship can be treated as verifiable metadata rather than a name string supplied at upload.
Three checks for three kinds of authority
The comparison yields three different prerequisites. These are review questions drawn from the reported cases, rather than a claim that one control fits every institution.
| Where the output appears | What the setting encourages people to trust | What needs checking first |
|---|---|---|
| Air-traffic decision support | A route suggestion is operationally useful | Performance under the intended conditions and the existing operating authority |
| Intelligence report | A conclusion follows from collected evidence | The source, the model's inference and independent corroboration |
| Author profile | A book belongs to the named writer | The link between the title, publishing account and verified author identity |
Put the check where the output gains trust
The check belongs at the particular handoff. Air-traffic support needs performance gates and fallback procedures before its advice changes operations. Intelligence work needs corroboration and source-level traceability before a conclusion supports action. Publishing needs a verified link between title and author, plus an appeal that reaches both the profile and the listing. Each follows the kind of trust the destination asks people to place in it.
A useful review question is: what must be true before this output enters the next screen or document? The answer might be a tested prediction, corroborated source or verified author identity. Make that prerequisite visible while someone still has the power to withhold authorization.
Newsroom has made the same distinction in its analysis of managerial judgment and accountability and in its argument that monitoring is not authority. Review works when a person can inspect the basis, identify what the system contributed, change the outcome, and leave an audit trail showing why.
Choose one trusted screen in a workflow you use and follow an entry backward. Can you find its evidence, the system’s contribution and the person allowed to challenge it? If the trail ends at the familiar format, you have found a useful place for the next verification step.